Source Reconciliation in AI-Generated Financial Reports
Verifiable sources, not plausible numbers, must anchor AI financial claims.
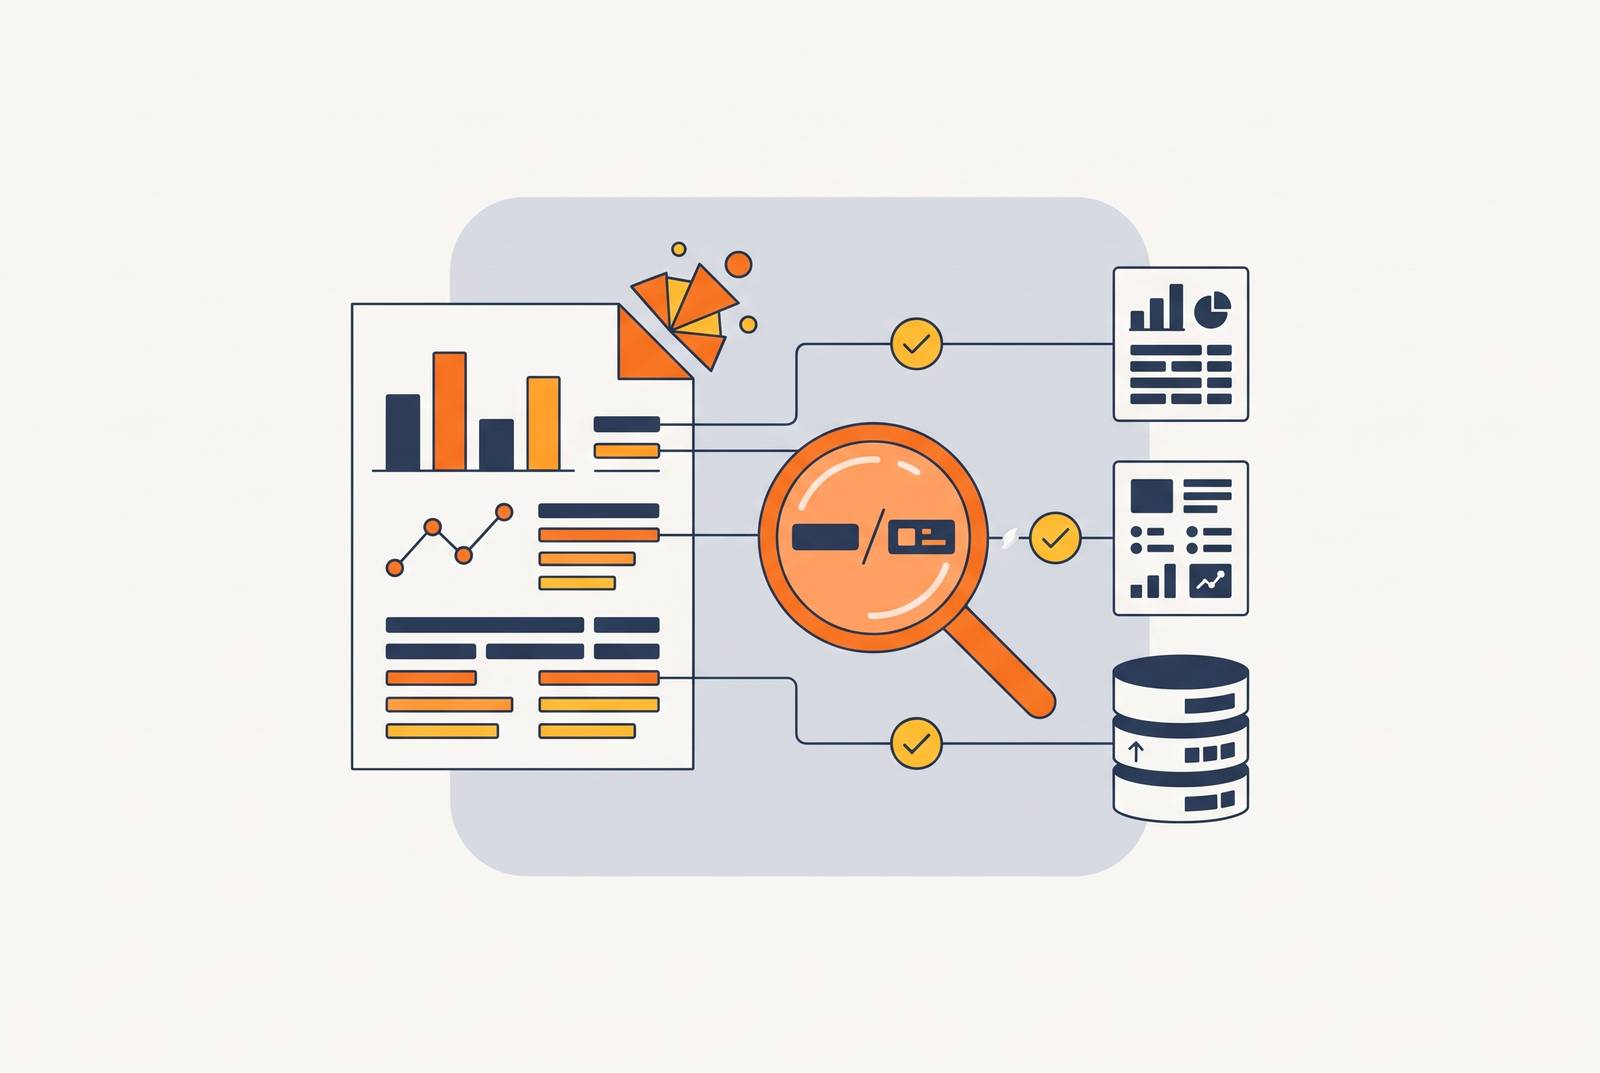
Source reconciliation in AI-generated financial reports turns a plausible number into a claim that can be checked. Every AI-produced figure must trace to a cited, retrievable source and match the value it claims to represent. A system must prevent unreconciled figures from reaching the report.
Why AI-generated financial figures cannot be self-certifying
Plausible and verifiable are different standards of evidence. An LLM generates text by predicting what fits and can read a ledger only if a system connects it to one. A financial figure can look right even when it matches no recorded value. Its appearance does not reveal the difference. Fluency establishes neither where a number came from nor whether it is correct.
Language models interpolate from training distributions, but transaction IDs, individual line items, and regulatory citations that change may fall outside those distributions. What, then, distinguishes a retrieved fact from a synthesized approximation? The output alone cannot establish that distinction. The surrounding system must preserve the evidence and enforce the connection.
What hallucination looks like when it reaches a financial report
Deloitte admitted in October 2025 that it used AI to help write a government welfare compliance report for Australia's Department of Employment and Workplace Relations. The report contained fabricated citations, and the firm had to refund part of its fee. Internal review did not prevent the citations from reaching publication. The case places the risk inside an established professional process.
Fabricated citations also illustrate why financial hallucination extends beyond an incorrect total. A report may present a claim with an apparent evidentiary basis that does not exist. Regulatory compliance questions are especially exposed because an answer must identify a specific statute or regulation. Where precision depends on a reference, a convincing reference is not enough.
The distinction changes what a reviewer needs. Reading for coherence can reveal contradictions, but it cannot establish that a cited document exists and supports the claim. That requires comparison with the source itself. The failure is therefore not evidence that review has no value. It shows why review without structural traceability is an incomplete control.
Source reconciliation defined: what the discipline actually requires
Source reconciliation sets a condition for inclusion in a financial report. Every figure must trace to a cited, retrievable source, such as a transaction ID, a regulatory filing, or an earnings report line. The system must enforce that condition. A source reference added after generation is insufficient if nobody or nothing compares the reported value with the evidence.
The standard has two inseparable components, citation and reconciliation. Citation identifies the specific source supporting a claim, while reconciliation establishes that the output figure matches the source value. A link alone satisfies only the first component. If the model misreads a line item and attaches the correct document, the figure remains unreconciled. Citation without verification is cosmetic compliance.
A transaction ID gives a reported amount a specific record against which it can be checked. Anaplan's CoPlanner and Detector Agent include source data, model, and timestamp for audit in every answer. Those details support an inspectable evidence trail. The architecture must require a figure to pass that check before it is accepted, even when the metadata is present.
Why grounding alone does not close the gap
Retrieval-Augmented Generation gives models access to evidence beyond their training data. That is a genuine improvement. For financial reporting, retrieval provides the filings, records, and other documents against which a claim can be assessed. But obtaining evidence and using it correctly are separate operations. A grounded answer can still contain a figure that the retrieved material does not support.
The gap is visible when retrieval fails or brings back evidence that is unclear. Many RAG systems still generate an answer, and the final presentation may not distinguish retrieved facts from synthesized content. Rewriting is not automatically a remedy either. Each regeneration can add an unsupported claim, especially when a calculation needs evidence that a single-source assumption leaves out.
FinGround's April 2026 paper addresses this problem through atomic claim verification and reports the lowest hallucination rate across its reported benchmarks. Its detection recall nevertheless drops to 71.4% for hallucinated values closest to the ground truth. Near-miss fabrications are the hardest errors to detect. A number can look reasonable to both a reviewer and a detector while remaining wrong.
The implication is not to abandon retrieval, but to stop treating it as proof. Reconciliation needs a separate check of each reported figure against its source value. Even that architecture needs a defined response when verification fails. Without refusal or exception handling, a number can still be published after the system finds reason to doubt it.
The five-layer architecture that makes source reconciliation enforceable
The requirements can be organized into five dependent layers, namely grounding, generation, atomic claim verification, audit, and governance. Grounding supplies the evidence on which the rest depend. FinBloom describes one way to build this foundation, using an external agent comprising a smaller LLM connected to real-time data sources to construct context for a primary LLM. Its pipeline consists of a Data Module, a Financial Agent, and an LLM. For time-sensitive inputs, the evidence must come from live retrieval.
Generation builds on that foundation to draft the financial output. It does not certify the result. The verification layer must treat each figure as a separate claim and compare it with the retrieved evidence. FinGround provides the relevant principle by decomposing answers into verifiable atomic claims. This separation prevents the act of writing an answer from also serving as its approval.
The audit layer preserves the comparison for inspection. Its record includes the source document, retrieved value, output value, and timestamp for each figure. Governance then determines what happens when those records show an unresolved claim. A figure that cannot be reconciled must not pass into the report. Human oversight operates on visible exceptions rather than an undifferentiated stream of polished text.
Deployment can follow a Crawl-Walk-Run sequence without weakening these dependencies. The crawl stage limits the system to one workflow with full human review and audit logging. Walking brings more work into scope and shifts review toward exceptions, with reconciliation rates checked before each expansion. Running lets the system work almost on its own, under governance that catches exceptions and logs source traces.
What real-time web grounding adds that static retrieval cannot
A figure can match its source and still be unsuitable for a current report. Earnings releases, regulatory filings, rate decisions, and market data change too fast for a fixed corpus to keep up. Freshness is therefore part of source fitness. A static index can support a claim about what was reported when it was built, but it cannot by itself establish the current value.
Live web grounding fetches evidence at query time. That gives reconciliation the current filing, rate, or regulatory text to work with, without assuming an older copy is still fit for use. What period does the report claim to describe, and does the retrieved evidence belong to that period?
Infrastructure evaluation consequently needs five criteria, including freshness, source diversity, latency under concurrency, compliance and data retention, and public benchmark accuracy. Freshness concerns when content was indexed or fetched, while source diversity concerns coverage of filings, news, regulatory databases, and financial data sources. Latency asks whether retrieval remains usable when many agents query simultaneously. Data retention is a compliance constraint. Query logging that conflicts with financial data-handling obligations can disqualify otherwise accurate infrastructure.
Publicly inspectable performance claims allow scrutiny, while self-reported runs still need to be recognized as self-reported. No ranking answers every infrastructure question. A grounding layer must meet the operational and compliance requirements as well as perform well on the relevant accuracy task.
How the regulatory environment turns source reconciliation from best practice into obligation
FinGround's regulatory analysis identifies August 2026 as the EU AI Act's compliance deadline for high-risk financial AI systems and emphasizes human oversight, interpretable outputs, and accuracy requirements. An untraceable number gives an overseer little basis for assessing its correctness. Source tracing makes the evidence available for that assessment. It also provides a basis for demonstrating accuracy.
FINRA's 2026 Annual Regulatory Oversight Report, published in December 2025, added a dedicated generative-AI section that explicitly names hallucinations. The report states that existing rules are technology neutral and apply to generative AI as they do to other tools. AI does not create a separate exemption.
These frameworks do not explicitly name source reconciliation as a universal technical prescription. The architectural implication is nevertheless direct. If a firm cannot establish where a reported figure came from or how it was checked, its account of oversight and accuracy is weaker. Choosing a vendor is thus a decision about both compliance and performance. The controls a financial workflow needs depend on how hallucination risk varies with the model and the task.
The optimism gap: why high executive confidence and caught errors coexist
Workiva's 2026 Midyear Executive Benchmark Survey found that finance, audit, and sustainability executives were broadly confident in AI outputs that appear in annual reports without human review. That confidence can coexist with errors passing through professional processes. The two observations describe different things. Confidence shows what people expect from a tool, while a fabricated citation shows where a particular evidence chain has failed.
AI output is fluent, formatted, and internally consistent, which can reduce the impulse to scrutinize it as closely as a junior analyst's spreadsheet. Presentation becomes a proxy for reliability. Yet the qualities that make a report easy to read do not establish that its references exist or its figures match them. Familiarity with polished outputs can therefore outpace the controls needed to validate them.
Asking people to be more skeptical cannot by itself resolve this reliance on presentation as a proxy for reliability. A reviewer needs accessible evidence and a clear account of what remains unresolved. Otherwise, verification competes with the apparent completeness of the document. A financial AI tool should show its reasoning through inspectable sources and comparisons. If a number cannot be traced to its source, it does not belong in a board pack.
Building source reconciliation into the workflow so it cannot be skipped
The practical response is to make reconciliation a system constraint. Each figure must be matched against retrieved evidence at generation time, and the comparison must be logged. The audit trail should keep the source document, retrieved value, output value, and timestamp. Unresolved citations must trigger a hard failure. A low-confidence flag still allows an unsupported figure to pass through a hurried review.
The same constraint must survive problems in the grounding layer. Stale evidence can produce a match against the wrong reporting period, while incompatible query retention can breach data-handling requirements regardless of accuracy. Slow retrieval also puts pressure on the workflow. If agents time out and fall back to training data, the system recreates the failure reconciliation was meant to prevent. The acceptance rule must remain intact when retrieval becomes inconvenient.
Implementation should begin with one bounded workflow, such as bank reconciliation or invoice matching, where source documents are structured and right-or-wrong outputs are unambiguous. Full human review and audit logging belong in this first stage. Reconciliation rates should be checked before more work comes into scope. A high match rate on clean records does not establish readiness for regulatory questions or multi-entity workflows. The system should get more autonomy only when the audit log shows that unresolved citations cause hard failures and stop silent degradation.
Reviewers can focus on exceptions the system could not reconcile, with the relevant evidence available for inspection. They need not repeatedly validate every routine match.