Competitive Intelligence Pipelines for Financial Analysts
Agentic pipelines deliver audit trails, not just answers, by grounding claims in live sources.
Competitive intelligence pipelines for financial analysts must do more than refresh a dashboard. They must retrieve live evidence, extract financial claims, reconcile conflicts, and deliver outputs that an analyst can audit. The central design principle is source-cited grounding. Faster intelligence becomes useful only when the analyst can trace each claim to the evidence behind it.
Why static CI dashboards fail financial analysts
An analyst working on a competitor briefing can have a dashboard that looks complete and still be missing yesterday’s most important disclosure. The saved filings are searchable, the charts are clear, and the report is ready to distribute. Yet a competitor’s new 10-Q remains invisible until someone refreshes the underlying store. The dashboard answers an older version of the question. In a fast-moving decision, that gap can make otherwise careful research unusable.
The gap stems from the architecture. Filings, earnings calls, regulatory disclosures, and company websites generate signals simultaneously, while manual research processes collect and distribute them in batches. A one-off retrieval-augmented generation query over saved PDFs inherits the same constraint. It can find only what has already been ingested. How much confidence should an analyst place in an answer whose evidence predates the event under examination?
With its first Magic Quadrant for Competitive & Market Intelligence Platforms in April 2026, Gartner formally recognized these platforms as an enterprise category of their own. That recognition provides context for the shift, but it does not resolve the underlying design question. The missing capability is a workflow that reaches current sources when the research runs, rather than waiting for a document collection to catch up.
What agentic CI pipelines actually do differently
An agentic CI pipeline receives a research objective and breaks it into executable subtasks. It identifies sources, retrieves live content, extracts claims, cross-checks figures, and synthesizes a structured answer within one workflow run. Unlike a chatbot that requires the user to manage each successive question, the orchestration layer directs the sequence.
This changes what retrieval means in the architecture. In static RAG, the model searches a fixed document store, so freshness depends on ingestion. In agentic RAG, the orchestrating model issues calls against the live web during execution. Freshness therefore depends on the sources retrieved at that moment. The workflow can also classify signals by strategic relevance, assign confidence scores, and flag uncertainty before delivering an answer.
Those capabilities help analysts judge what a competitor’s actions might mean as well as describe what it did. They do not make prediction certain. Instead, they organize evidence for a judgment that remains open to review. Distribution changes as well, with a scheduled call able to trigger a competitor briefing delivered just before it begins. Because the result depends on several linked operations, no single model or interface can compensate for a weak component elsewhere in the chain.
The four components a financial-grade CI pipeline requires
Live retrieval is the first layer. A pipeline investigating a competitor’s latest disclosure must reach the filing submitted today, rather than a cached representation of yesterday’s information. Retrieval also has to fit inside the workflow’s time budget. If each search delays the next operation, the search layer becomes a bottleneck even when its results are relevant.
A financial table loses its meaning if its values are separated from their row labels or footnotes. Passing that flattened text to a model does not restore the missing relationships. The extraction layer must therefore handle tables, body text, and cross-referenced figures in document-heavy sources, including filings, investor decks, and lengthy PDFs.
If a filing and another source give conflicting revenue figures, the pipeline must detect the conflict and check the numerical claim against the primary document. Confidence scoring shows how strong that evidence is. Unresolved differences belong in the output.
Cited output completes the chain with a reviewable deliverable. In a competitor tear sheet, a revenue claim must trace to the relevant sentence or table. The excerpt is the unit of evidence. This connection makes the output useful both to the analyst evaluating the claim and to the reviewer examining its provenance.
Why source citation is the non-negotiable foundation, not a nice-to-have feature
Financial intelligence needs a basis for trust. An unsourced answer gives the analyst no reliable way to assess its confidence, locate an error, or explain its use to a compliance reviewer. Fluent wording cannot supply that missing basis. Grounding against live sources addresses factual reliability, while precise citations make the grounding inspectable.
Citation performs three distinct jobs in that inspection. Error traceability lets an analyst follow a questionable claim back to its source and determine where the interpretation went wrong. Confidence calibration distinguishes evidence from a primary filing from a claim repeated by a secondary aggregator. An audit chain documents provenance for internal risk teams and regulators.
Could analysts with experience just spot hallucinations themselves instead? They can often recognize obvious errors in familiar domains, but competitive intelligence spans companies, geographies, and regulatory regimes beyond any one person’s detailed knowledge. Requiring them to independently reconstruct every answer would restore the manual bottleneck the pipeline was meant to remove. Citation gives review a tractable starting point, so provenance must survive retrieval, extraction, and reconciliation.
What breaks when the retrieval layer is weak
A stale retrieval layer can produce an answer that is cited yet wrong for the present decision. If a competitor’s 8-K filed this morning never reaches the workflow, the model may accurately summarize an earlier situation. Every downstream step then works from an obsolete premise. Better prose or a more capable model cannot expose evidence the pipeline never retrieved.
Incomplete extraction creates a different failure. A URL and a search snippet may identify a relevant filing without exposing the footnotes needed to interpret its headline figures. The model is then asked to reason across a gap in its evidence. Converting every retrieved document into unstructured text is not a sufficient remedy, because it increases token costs and can degrade accuracy by obscuring the document’s structure.
Rogo’s use of structured financial retrieval and targeted model choices, including Gemini 2.5 Flash, illustrates the potential improvement. The reported direction is a substantial reduction in hallucinations. Retrieval quality is a lever. Evaluation must therefore assess both the model’s answer and whether the evidence supplied to it is current, complete, and usable.
How to evaluate search APIs for financial CI use cases
Freshness means reaching relevant filings, news wires, and investor pages during execution. Extraction depth means getting the document’s structured content. Output format also counts, because raw HTML leaves parsing work to the agent that a structured, cited response can avoid.
Financial accuracy requires its own test conditions. General web search scores do not establish performance on difficult questions about filings or financial figures. Domain-specific evaluation provides a closer comparison. Production evaluation must also examine stable latency, error rates, and cost across repeated calls, rather than treating a fast demonstration as proof that the API will fit an agentic workflow.
You.com’s Finance Research API has FinSearchComp leadership as benchmark evidence for its financial-domain accuracy claim. That is a reason to include it in a workload-specific evaluation. Its broader suite provides distinct endpoints for different pipeline jobs, including the Web Search API, Answer API, Contents API, Research API, and Finance Research API. Teams can thus test search, extraction, grounded answers, and research on their own. Evaluate how well each serves the financial workflow.
Designing the pipeline as a step-by-step architecture for financial CI
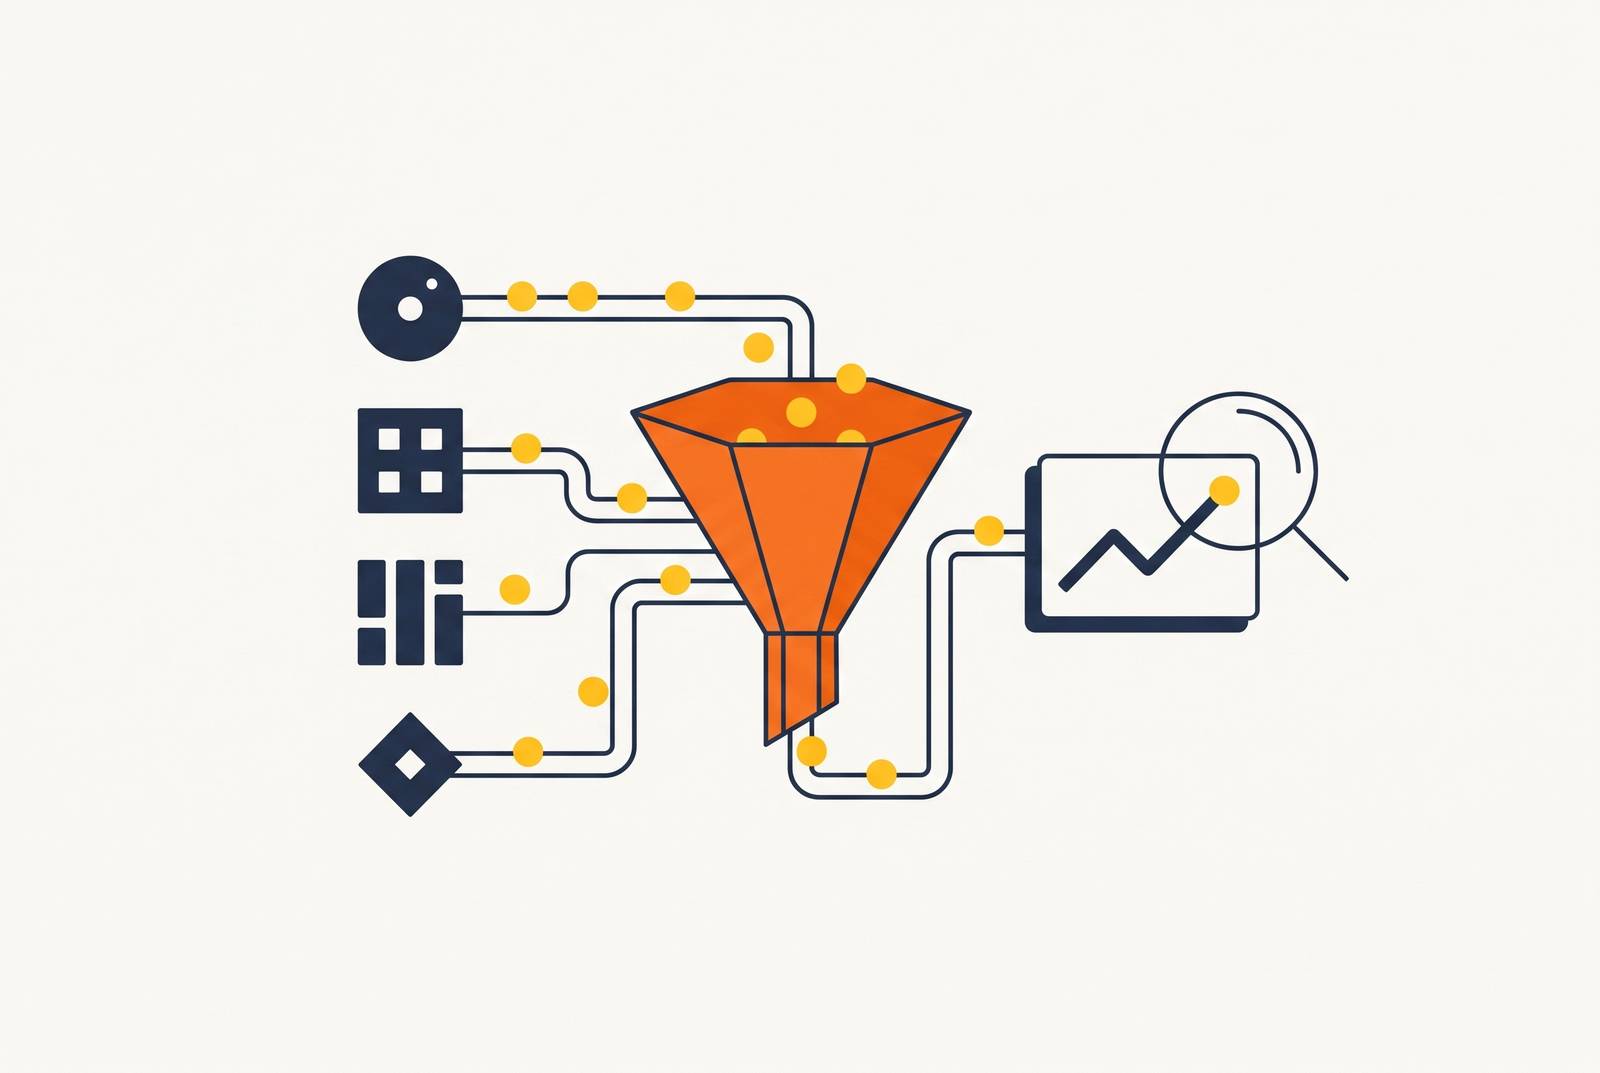
To put those criteria into practice, consider monitoring a logistics competitor for M&A signals. The design starts by setting out which competitors, counterparties, sector peers, and regulatory bodies to cover. Trigger conditions can include new filings, earnings transcripts, leadership changes, and material news. Scheduled sweeps and event-driven triggers meet different needs. The architecture should support both, so a regular monitoring cycle does not become the only route by which a new disclosure enters the workflow.
Next, the agent issues structured queries against primary sources, including SEC EDGAR, investor relations pages, and regulatory agencies. A live search endpoint such as the Web Search API maps to this step. Results need source metadata, including the URL, publication timestamp, and source type. Those fields give reconciliation the context it needs to compare evidence.
The extraction step then fetches the full documents. For the logistics example, a retrieved filing must become structured body text, tables, and footnotes. The Contents API maps to this fetch-and-extract layer. Keeping extraction discrete also makes it testable without treating every failure as a problem with the final prompt.
Reconciliation follows by comparing claims across the extracted sources. Claims about numbers are checked against primary filings, while evidence that conflicts or is uncertain is flagged with confidence information. A possible M&A signal remains uncertain when the documents do not settle it. The pipeline should not silently select the interpretation that makes the briefing read most smoothly.
The output step creates a competitor brief, tear sheet, or monitor alert with citations. Parallel’s finance use case shows how this works, with tear-sheet claims linked to excerpts from filings, investor decks, or lengthy PDFs. Delivery can use structured JSON for programmatic consumption or a human-readable brief for direct review. Finally, the intelligence is pushed into the analyst’s workflow through a Slack alert, CRM note, or dashboard widget, rather than waiting in another database to be discovered.
Compliance, security, and governance requirements that financial CI pipelines must satisfy
The external calls in that architecture create a concrete security question. What sensitive client information, deal context, or proprietary research would leave the organization when the agent constructs a query? Financial deployments must address that exposure at the retrieval and extraction boundary. A zero-data-retention model belongs in the infrastructure requirements.
SOC 2 Type II and ISO 27001 form a minimum qualification threshold for the infrastructure described here. SOC 2 Type II addresses ongoing adherence to Trust Services Criteria, with security mandatory and other criteria dependent on scope. Scope therefore deserves attention during evaluation. A certification label alone does not spell out every control that matters to the planned workflow.
Auditability reaches across the steps already defined. Every retrieval call, extraction result, reconciliation decision, and output must be logged in a traceable audit trail that the pipeline can produce automatically. This requirement connects the system’s execution history to its cited deliverable. Without that connection, a reviewer may see the final evidence but not how conflicting claims were handled.
For teams concerned that external APIs cannot handle sensitive financial work, zero-data-retention terms and security certification provide an architectural response. You.com offers these terms as options on enterprise agreements. Zero data retention must be requested explicitly. It is not enabled by default, so deployment planning must distinguish available contractual terms from the settings actually in force.
How CI pipelines change the analyst's role rather than replace it
When retrieval, source tracking, and formatting take less time, the analyst’s work shifts toward framing and judgment. Defining the right research objective becomes more valuable because it determines what the agent investigates. Analysts can focus their checks of the evidence because claims come with provenance and confidence information. Strategic synthesis then connects those claims to the decision at hand. None of these tasks is completed by retrieval alone.
The organizational objection is that AI lacks social context and nuance, particularly in credit or risk decisions. Agents should work under rules and oversight to support decisions, with people who are accountable approving material decisions. The analyst must understand where the evidence came from, how conflicts were reconciled, and what a confidence score does and does not establish.
In practice, this replaces a queue of static report requests with natural-language access to grounded intelligence and surfaced exceptions. The analyst need not spend the same effort assembling the evidence before asking what interpretation and response it warrants. For the logistics competitor, that question concerns how strongly the evidence supports a strategic interpretation of an M&A signal and what response that interpretation warrants. The final decision belongs to an analyst with fresher evidence, clearer provenance, and more room to think.