Reranking Web Search Results for LLM Context Windows
Reranking filters noise from initial search results to deliver cleaner context for language models.
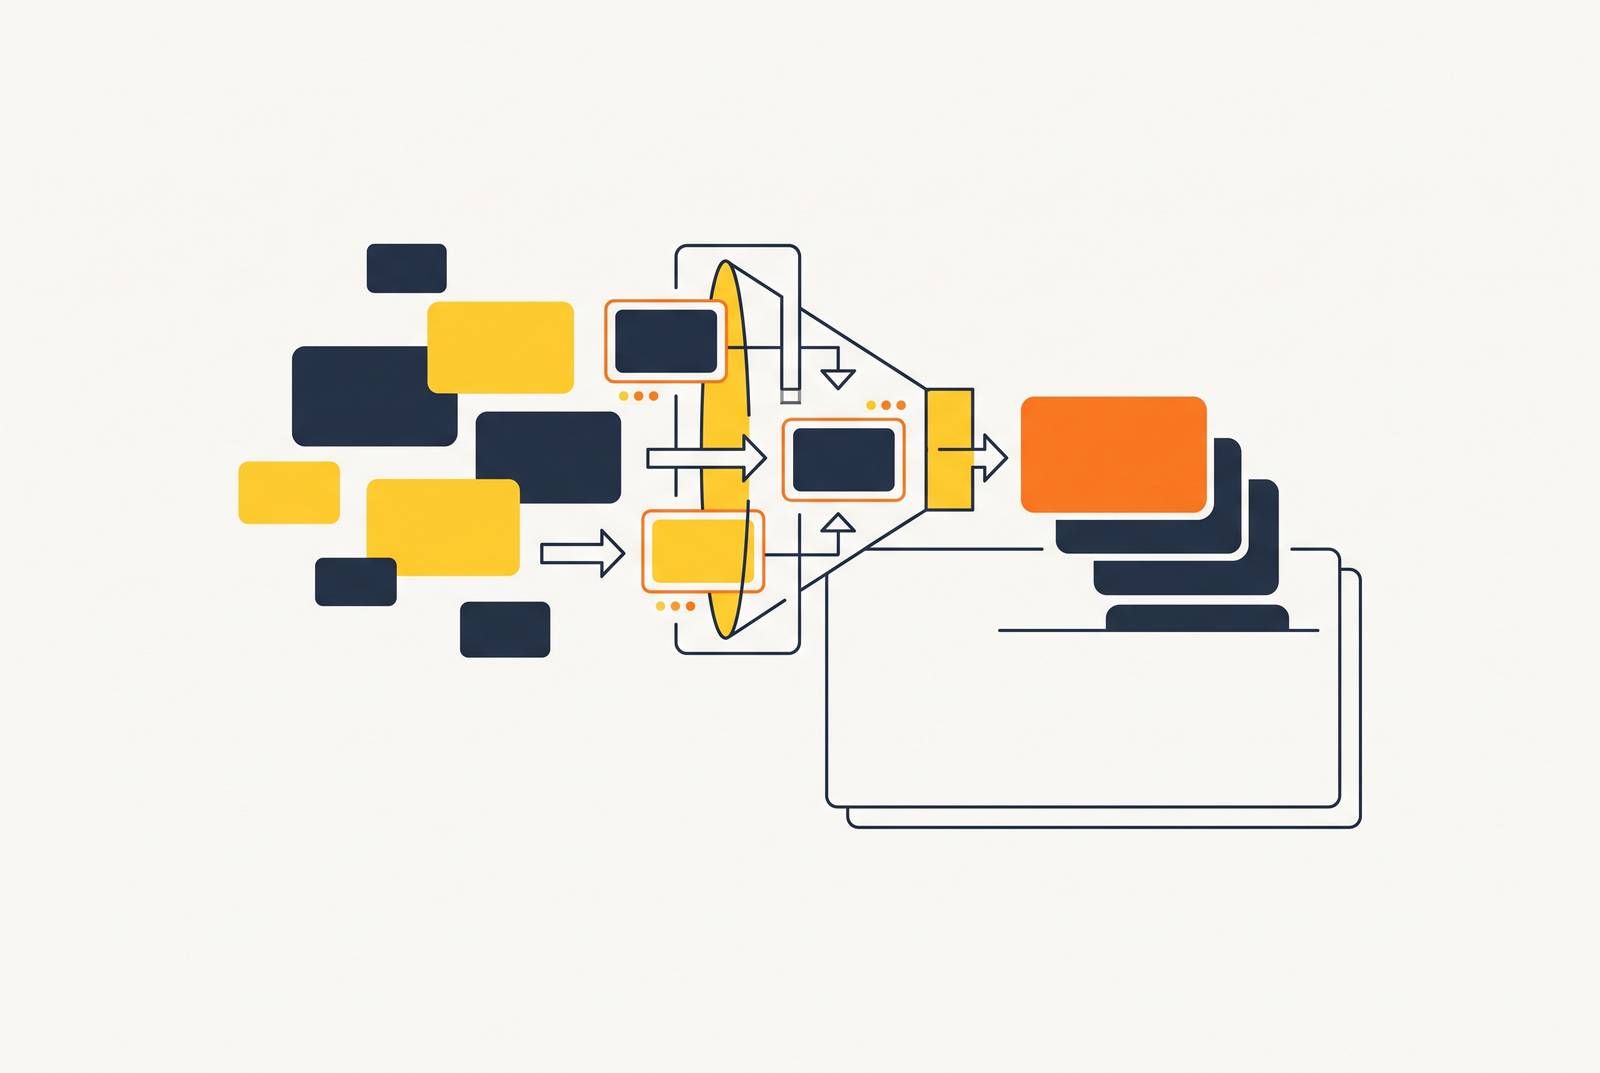
A single retrieval pass returns a candidate set that is both too large for the context window and too noisy for reliable reasoning. Reranking is the second stage that transforms that noise into a compact, high-relevance input for the model. Getting it right means understanding what each layer of the pipeline contributes and where each one fails.
Why first-pass retrieval alone cannot fill an LLM context window reliably
Every LLM context window is finite, and every document injected into it competes with every other document for the model's attention. When a single-stage retrieval pass returns hundreds of candidates and all of them enter the prompt, the model must reason over irrelevant material alongside relevant material. The result is the degradation pattern known as "lost in the middle," where important passages buried among distractors fail to influence the answer.
The two dominant first-pass methods fail in opposite and complementary ways. Dense vector search maps query and document into a shared embedding space and retrieves semantically similar documents even when surface terms differ, but it underweights rare exact-match terms such as product codes, entity names, and regulatory identifiers. A query for "Apple security issues" sent through BM25 alone returns fruit-storage articles rather than cybersecurity documentation.
Neither method wins across all query types. The practical consequence is that pipelines treating first-pass retrieval as the final step fail at a high rate, not occasionally but as the default outcome on diverse query sets. So the candidate set needs a second stage of selection before anything enters the prompt.
How hybrid retrieval combines sparse and dense signals into a single ranked candidate set
Hybrid retrieval fuses BM25 and dense vector search so each method covers the query types that break the other. Dense retrieval uses approximate nearest-neighbor search over embeddings to find semantically similar documents even when surface terms differ. Each method supplies what the other cannot.
The problem is that their scores are incompatible. BM25 scores are unbounded positive real numbers, while cosine similarity scores are bounded in the range [-1, 1]. Reciprocal Rank Fusion resolves this by operating on rank positions only, not raw scores, so no normalization is required and no per-query tuning is needed. Empirical benchmarks on the WANDS e-commerce dataset show that a well-tuned hybrid reaches a meaningfully higher NDCG than either BM25 or KNN alone.
Vendor support for RRF diverges in ways that affect stack selection. Qdrant added server-side RRF natively in v1.10. Elasticsearch requires a Platinum or Enterprise plan for native RRF, and the free workaround is client-side RRF implemented in application code, either through the ranx Python library or a short custom function.
The correct architecture that follows from hybrid retrieval is a two-stage pipeline: first-stage ANN retrieval of a top-N candidate shortlist, then a second-stage reranking pass on that shortlist. Cross-encoders cannot scan millions of documents at query time. The shortlist still contains noise, and the reranker exists to remove it before anything reaches the prompt.
What reranking actually does to the candidate set and why it reduces LLM hallucinations
Reranking rescores each candidate against the query with a model that is too expensive to run at retrieval scale. The passages that enter the context window are therefore ordered and filtered by genuine relevance rather than approximate similarity. Cross-encoder rerankers process the query and document pair jointly, which lets them model much deeper interaction.
This "geometric bottleneck" in fixed-dimensional embeddings is a fundamental limit on what similarity-based retrieval can express. The reranker can model causality, analogy, and conditional relevance that a vector norm cannot. When "Apple security issues" is routed through BM25 and the fruit-storage articles appear, a reranker on the same candidate set correctly elevates the cybersecurity documentation because it understands the full query-document pair in context.
Reranking is also the stage at which context representation choices are made: whether to pass title only, first sentence, or full passage text up to a character limit to the scorer. Those choices affect accuracy and latency in measurable ways. The outcome claim is straightforward: a reranked context window contains more relevant material and less noise, and an LLM reasoning over a cleaner context produces fewer unsupported claims.
The three reranker architectures and the accuracy, latency, and cost trade-offs each introduces
Cross-encoders, listwise LLM rerankers, and instruction-following rerankers occupy distinct positions on the accuracy, latency, and cost curve. Choosing the wrong one for a workload is a deployment failure waiting to happen. Each architecture wins in its context, and the decision matrix maps those contexts.
Cross-encoders score query-document pairs jointly and cannot pre-compute document representations, so they are inherently a shortlist operation. Databricks benchmarks show 50 documents reranked in 1.5 seconds with a parallelized reranking architecture, a concrete latency anchor for capacity planning. The best fit is production search, high-traffic RAG pipelines, and latency-sensitive agents. Listwise LLM rerankers take the full candidate shortlist as a single prompt and output a ranked ordering, inheriting the long-context reasoning of the backbone LLM. The best fit is offline processing, research pipelines, and low-throughput workloads where accuracy is paramount.
Instruction-following rerankers allow practitioners to prepend natural-language instructions that steer relevance judgment, such as "prefer results that include regulatory references." Voyage rerank-2.5, released August 11, 2025, introduced instruction-following capability with a 32K token context window, substantially larger than Cohere Rerank v3.5's context, enabling it to handle longer candidate passages without truncation. The vendor states an accuracy lift over Cohere Rerank v3.5 across a 93-dataset suite, but that is an input to verify against independent benchmarks, not a settled result. The best fit is domain-constrained retrieval where query-agnostic relevance scoring is not sufficient: compliance, finance, and regulated-industry RAG.
Candidate set sizing is a latency lever in its own right. Rerank roughly 50 documents for LLM chat applications where speed matters, and 100 to 200 for comprehensive web search where thoroughness takes priority over milliseconds. Doubling the candidate set doubles processing cost but yields diminishing relevance returns beyond a hundred candidates in most domains, with the sweet spot between 50 and 75 documents.
An emerging middle ground deserves attention. A 3B-parameter model achieves competitive listwise performance, and training with attention heads from middle layers reduces latency without performance loss. The approach outperforms existing pointwise and listwise rerankers on Wikipedia, long narrative datasets, and multi-hop QA benchmarks including MuSiQue and HotpotQA. It is a practical path to LLM-quality ranking at cross-encoder speeds.
When query intent requires more than scoring — using query decomposition to guide reranking
For queries where relevance depends on latent intent rather than surface terms, particularly superlative and comparative queries, decomposing the query into structured attributes before reranking produces substantially better ranking than scoring the original query against raw candidates. Superlative queries such as "best" or "most popular" delegate the burden of domain-specific evaluation to the search system. Without decomposition, the reranker has no concrete criteria against which to score candidates.
The Hint-Augmented Re-ranking system from Amazon decomposes superlative e-commerce queries into attribute-value hints. For "best balloons for birthday parties," it generates hints such as color variation, durability, material quality, and age appropriateness, and generates those hints concurrently with retrieval so hint generation adds no wall-clock latency. The result is meaningful improvements in MAP and MRR over baselines on a dataset of tens of thousands of queries and hundreds of thousands of products.
The broader principle is learned query augmentation. Instruction-following rerankers are the deployment-time equivalent. Where hint extraction generates structured criteria programmatically, instruction-following lets practitioners specify those criteria manually as natural-language prompts, which is useful when query categories are known in advance.
How agentic and multi-hop retrieval pipelines change the reranking calculus
Classic RAG makes one retrieval call and one LLM call. Agentic RAG in 2026 makes multiple dynamic retrieval calls per turn with multi-hop reasoning, sometimes with a faithfulness judge gating each answer before continuing. A complex query resolved across multiple retrieval rounds with full reranking at each round can cost orders of magnitude more than a simple query resolved in one round, and that cost scales with task complexity, not query count.
The DS@GT TREC ToT 2025 system demonstrates what is required. It fuses BM25, dense retrieval, and LLM-based retrieval at the retrieval layer, then reranks with PageRank graph centrality as a feature. Reranking configuration itself becomes a variable the agent optimizes, not a fixed hyperparameter set at deployment time.
The practical implication for developers is that reranking architecture choices made for a synchronous RAG pipeline become prohibitively expensive inside an agentic loop. An always-on listwise LLM reranker is the wrong default. Cross-encoders or lightweight attention rerankers are typically the right choice for per-hop reranking, with LLM reranking reserved for a final synthesis pass if needed.
Connecting the pipeline to live web search: what changes when candidates come from the open web rather than a fixed corpus
When the candidate set comes from live web search rather than a pre-indexed corpus, freshness, source diversity, and infrastructure reliability become first-class pipeline concerns alongside the reranking accuracy trade-offs already established. The open web does not. BM25 parameters tuned on internal data may not transfer, and dense retrieval models trained on static corpora may underweight recent terminology.
The web grounding use case is broad. Developers use web search APIs to power RAG pipelines, ground LLM outputs in real-time sources, run competitive research at scale, and feed agents with live web context mid-task. Three architectural patterns for injecting live web results each carry a different reranking implication. In a hybrid pattern, a static knowledge base plus live web search is routed by query type, and the reranker must handle candidates from heterogeneous sources with different freshness and format characteristics. Production workloads that had relied on Bing were forced to migrate on short notice, and teams building grounding pipelines now need to evaluate web search API options carefully for ecosystem lock-in risk.
You.com's Web Search API, Contents API, Answer API, Research API, and Finance Research API are built specifically for this pipeline layer. The Research API previously claimed the top benchmark position on DeepSearchQA, though it has since been surpassed on current leaderboards, and the Finance Research API ranks first on FinSearchComp's T2 and T3 sub-tasks. Those are published benchmarks that give developers a verifiable basis for comparison rather than vendor claims alone.
Security and compliance requirements that a reranking pipeline must satisfy in enterprise deployments
Reranking pipelines introduce attack surfaces and compliance requirements that differ from those of a standard LLM deployment. Retrieval poisoning occurs when manipulated content injected into the vector database or web index gets surfaced by retrieval and passed to the reranker, and then into the LLM context, before any content moderation layer can intervene. Embedding inversion is the possibility that sensitive source documents can be reconstructed from vector embeddings stored in the index.
The architectural counter-measure is permission-aware retrieval, which filters candidate documents against the requesting user's entitlements before any document reaches the reranker or the model. SOC 2 auditors in 2026 now probe training data provenance, model bias, and agent permissions under existing Trust Services Criteria, not just infrastructure controls. Generic penetration tests miss prompt injection, RAG leakage, and agent misuse that auditors now expect to see addressed. For regulated-industry buyers evaluating enterprise grounding APIs, the relevant axes are configurable index freshness, evidence density, source diversity, zero data retention policy, and SOC 2 certification as a baseline expectation, not a premium feature. You.com offers optional zero data retention on enterprise agreements on request and holds SOC 2 Type 2 certification.
Evaluating the full pipeline: what good benchmarks measure and where current measurement falls short
A pipeline that optimizes for vendor benchmark scores without measuring the dimensions that matter for its specific workload is optimizing for the wrong thing. A useful retrieval and reranking benchmark must first fix the query set, then measure relevance, freshness, latency, output completeness, failure rate, and effective cost. Vendor claims should be treated as inputs to verify, not as measured results.
The standard metrics each capture a different property. MRR, mean reciprocal rank, measures how quickly the first relevant result appears and is most informative for known-item or single-answer retrieval tasks. Recall@k measures what fraction of all relevant documents appear in the top-k and is the right metric for evaluating the retrieval stage before reranking, since a reranker cannot recover a relevant document the retrieval stage never returned. The DS@GT TREC ToT 2025 system achieved recall of 0.66 and NDCG@1000 of 0.41 on the test set.
Current benchmarks leave important dimensions unmeasured. A pipeline that scores well on NDCG@10 may still produce uncited or incorrectly attributed answers at the LLM output layer. The Financial RAG case establishes what domain-specific benchmarking looks like in practice. The Hierarchical Reranker framework that placed second in the ACM-ICAIF '24 FinanceRAG Challenge used NDCG@20 as its primary metric and coupled it with deterministic pre-retrieval optimization and adaptive long-context management. Domain-specific pipelines require domain-specific evaluation.
The practical step is to build an offline evaluation harness against a query set that reflects the actual workload distribution before committing to a reranker architecture. Architecture choices that look equivalent on public benchmarks often diverge sharply on domain-specific query sets. The pipeline this article has walked through is only as good as the evaluation layer that tells developers whether it is working.