Caching Strategies for Search API Calls in Agent Workflows
Match cache TTLs to how fast your search data actually changes.
Search API caching in agent workflows is a freshness problem before it is a storage problem. The right strategy fits exact-match, semantic, and tool-result caches to how fast the data behind each query changes. One policy for all queries either reuses evidence that can no longer be trusted or pays again for information that is still valid.
Why search API caching in agent workflows is a different problem from web caching
In web engineering, invalidation often follows a known change to a file or database row. Search results come from a source outside the application’s control, with no webhook from the live web. A cached result can become unreliable because a source document changed, knowledge moved on, or the task now requires a different time frame. Correctness therefore depends on more than whether the stored response has expired.
That uncertainty grows over long-horizon agent tasks, where a conversation can run through dozens of API calls as its context windows grow. Each repeated search adds latency and another billable operation, even when its intent matches an earlier request. Data infrastructure can cost far more than LLM inference, so token optimization alone falls short. Yet removing repeated calls indiscriminately undermines the reason for searching in the first place, which is to ground answers in current, cited evidence.
The three cache tiers available to an agent's search pipeline and what each one does
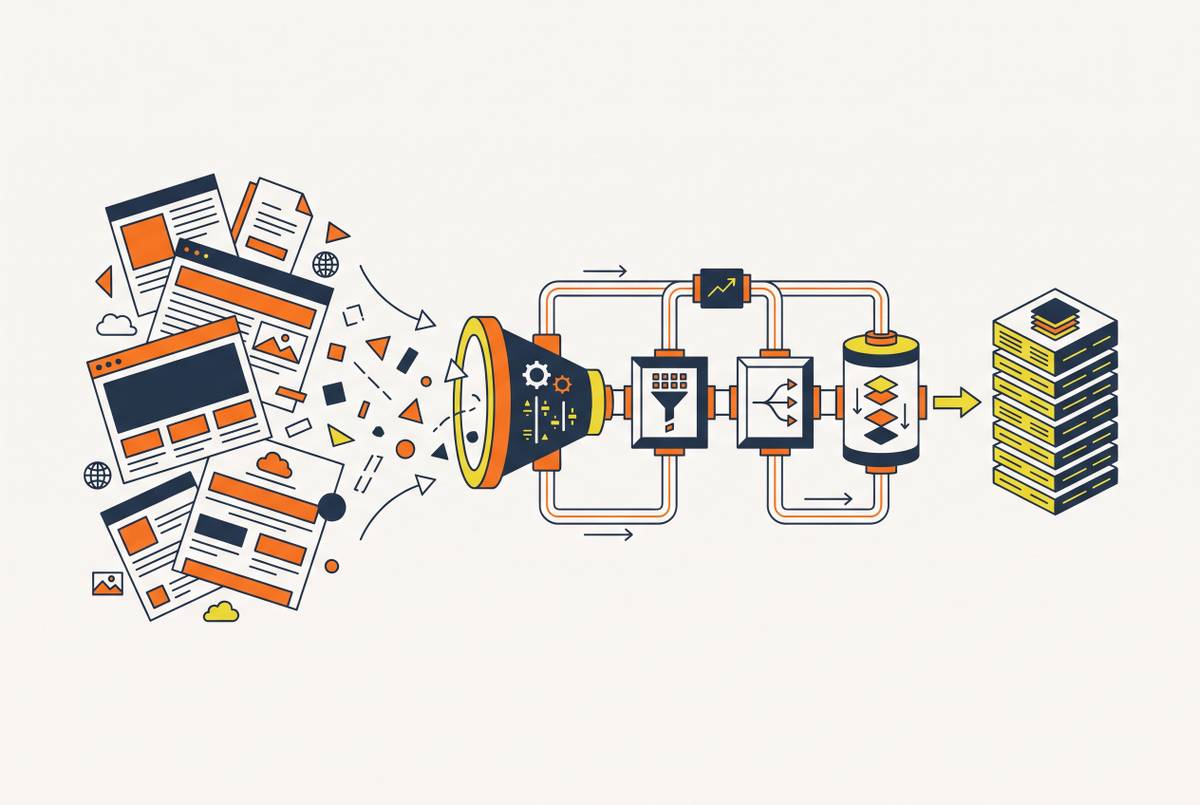
An exact-match cache associates a precise query string with its result. Lookup is sub-millisecond, and implementation cost is lowest among the three tiers. This makes it the first layer to deploy. It catches repeated formatted queries in structured tasks, but natural-language variation limits its reach in conversational work.
A semantic cache matches what a query asks for. It embeds an incoming query and searches cached embeddings for a sufficiently similar question. Different wordings can therefore reuse the same result. Three agents asking about the same entity’s Q3 performance, for example, can resolve to one API call. Similarity, however, is a configurable judgment.
A tool-result cache stores the output of a specific tool invocation for a defined time to live, or TTL. Its role is narrower than interpreting intent. It prevents repeated network calls when multiple agent steps or concurrent agents need the same data. The Morgan State University hierarchical caching study identifies redundancy at both workflow and tool levels, explaining why these tiers complement one another.
How to classify queries by volatility before assigning any TTL
Before writing cache code, the engineer must ask how fast the information being asked for can change. Volatility belongs to the data. Live stock prices, sports scores, active incident feeds, and inventory counts change too fast for a useful TTL to keep up. These form the real-time band, where reuse is inappropriate. Pricing pages, earnings announcements, and breaking news form a market-sensitive and current-events band because changes in them can make evidence too old to use within minutes.
Operational support and product documentation change less often, so they can be reused for hours within a session or workday. Definitional and reference content, including glossaries, regulatory text, and academic papers, supports day-range reuse because changes are infrequent and often versioned. These distinctions apply to individual tool calls. A research task may cross all four bands, so a workflow-wide label is too coarse. Personalized queries add another condition, as a session ending or user state changing can invalidate a result independently of topic volatility.
Assigning TTLs to each cache tier based on query volatility class
Real-time queries should skip all three search-facing tiers and leave no entry in the cache. A one-minute TTL adds write overhead and can serve stale evidence immediately before expiry, while offering negligible useful reuse. Exact-match and tool-result caches should enforce this directly, and semantic matching must not override it.
For market-sensitive and current-events queries, minutes-range TTLs fit the limited window in which repetition is useful. Exact-match and tool-result caching are appropriate within that window, while semantic reuse demands care around different time frames. “Yesterday’s close” and “today’s open” may look similar without asking for interchangeable evidence. A semantic hit must inherit the matched entry’s volatility class.
Operational and documentation queries support hours-range tool-result and semantic TTLs, with exact-match TTLs at the same or longer duration where validity permits. Their varied phrasing makes semantic reuse especially useful. Stable reference content supports the longest, day-range TTLs across the tiers, supplemented by invalidation when a document version changes. For the middle bands, stale-while-revalidate can return a still-useful cached result immediately and refresh it in the background for the next caller.
Implementing exact-match caching for agent search calls
Exact-match caching establishes a baseline without requiring vector infrastructure. The key should begin with a normalized, canonicalized query rather than raw user input, so trailing whitespace or capitalization does not create unnecessary misses. Hashing that representation with SHA-256 keeps keys compact. The key must also include the search endpoint and parameters that affect the result, including region, language, and freshness window. Otherwise, identical wording can collide across requests with different scopes.
Store TTL alongside the value so expiry can be enforced at read time without a separate sweep. For most entries, time-based expiry is sufficient. Reference content also needs signals when a document or data source changes if a version change makes the content invalid. This design works especially well for generating reports, checking status again and again, and tracking competitors in a fixed format. Free-form research exposes its limit, because an equivalent question expressed differently still produces a different key.
Implementing semantic caching for queries where phrasing varies but intent is stable
Semantic caching trades stricter identity for broader reuse, making its similarity threshold the central correctness decision. Too permissive a threshold returns answers to genuinely different questions. At 0.75, that risk can outweigh the savings. At 0.99, the hit rate can collapse toward the exact-match baseline. A practical target is around 0.92–0.95 on well-tuned embeddings, but teams should validate it against their own query distribution.
The implementation embeds each incoming query and runs approximate nearest-neighbor search against cached embeddings. A qualifying match returns the stored result with its TTL class. The embedding’s age alone cannot establish freshness. Teams that already use a vector database for RAG retrieval can reuse it, but they still need an expiry policy for search. Queries with time anchors such as “current,” “today,” or “live” should route to a real-time bypass regardless of similarity, because linguistic resemblance cannot establish temporal equivalence.
Implementing tool-result caching at the search API call boundary
At the tool boundary, a cache hit avoids a billable API call. The key should represent the fully parameterized invocation, including the query, endpoint, region, date-range flags, and other result-affecting parameters. Scope must remain part of the identity. The tool definition should hold the TTL policy, including a bypass flag for real-time data, so the framework can enforce it consistently across agent instances rather than leave it to scattered application decisions.
For operational and stable reference queries, the standard cache-aside pattern applies, with the refresh and invalidation supplements their volatility classes require. Results for a specific user also need session isolation in multi-tenant deployments. A valid result is not necessarily a shareable result. The same study uses automatic session scoping to preserve isolation under concurrent tenant load, linking this implementation choice directly to privacy controls. More advanced dependency-aware invalidation becomes relevant when an agent’s writes change the validity of cached reads.
How provider-side prompt caching interacts with search tool results — and where the boundary must go
Search-layer caching does not control how an LLM provider caches prompt computation. Provider-side prompt caching reuses computed KV tensors for repeated prefixes containing system instructions, context documents, tool definitions, or examples. It saves prefill work. PricewaterhouseCoopers evaluated prompt caching across OpenAI, Anthropic, and Google over more than 500 agent sessions on DeepResearch Bench and found API cost reductions of 41–80%.
However, the evaluation also found that naive full-context caching can increase latency. Dynamic tool calls and results trigger cache writes for content that will not be reused across sessions. Cache static system prompts and tool definitions while placing dynamic tool results at the end, outside the cached prefix, or explicitly excluding them from the cache block. Search-result reuse already belongs to the tool-result TTL policy. Teams should validate boundary behavior against their provider and model because the evaluation found differences between providers’ strategies.
Freshness requirements for search APIs that provide real-time grounding
A cache miss only helps if the live response is sufficiently current. A TTL policy cannot bring an old source index up to date. Some APIs return real-time web content, while others serve an index that is refreshed from time to time. That distinction shapes which freshness bands the pipeline can support and how much confidence a bypass provides.
Microsoft retired the Bing Search APIs on August 11, 2025, directing developers toward “Grounding with Bing Search” inside Azure AI Agents. Such integration choices affect where teams can control freshness and caching in their pipelines. Alongside retrieval quality, engineers must assess whether live calls provide current evidence, whether their latency supports bypassing reuse, and whether their data handling fits enterprise requirements. For financial and market-sensitive searches, source-reconciled, cited output makes the response verifiable when the shortest-TTL or bypass policy sends a request to the API.
Cache invalidation beyond TTL: event-driven and dependency-aware patterns
TTL limits age, but it cannot detect a specific change that makes a result invalid before expiry. When a knowledge base article, regulatory filing, or product page changes, results that refer to its old version must be evicted. An agent’s own writes create another trigger. Filing a ticket or updating a record can invalidate cached reads that depended on the prior state, even when those reads were made moments earlier.
For workflows that write as well as read, dependency-aware tracking can connect cached entries to the data they rely on. The same architecture uses a graph to propagate invalidation across affected entries. That complexity has a specific purpose. It is warranted when writes can change cached reads, rather than as a default addition to every search cache.
A result drawn from a document the user can no longer access must be evicted regardless of remaining TTL, with session scoping and authorization checks at read time providing the relevant controls. Stale-while-revalidate leaves the permission issue unresolved. TTL should remain the default expiry mechanism, supplemented by event-driven invalidation for changes that time alone cannot detect.
Compliance and data privacy requirements that constrain cache design in enterprise agent stacks
An enterprise cache is a data store with retention and access obligations. Data flow mapping must cover what the tool receives, what the cache stores, how long entries remain, and whether they cross session or user boundaries. Those choices have DPA and privacy notice implications. Cached personal data or confidential source material must be accounted for in the relevant subprocessor data flows.
SOC 2 covers infrastructure access controls and data protection, but leaves open what an AI system does once it is connected to data. Reading and indexing have a different risk profile from writing records or sending messages. Entries that mix those activities take on the higher risk class. Teams should enforce session isolation, map cache retention to provider DPA terms, prevent audit logging from putting PII into shared stores, and check revoked access at read time.
A provider’s optional zero data retention arrangement can simplify the live-call tier’s DPA obligations, but it does not remove the application’s stored copies. Responsibility remains with the team operating the cache. The practical limit on reuse is therefore the earliest point at which evidence becomes stale, context changes, or access ends. Layered caching earns its savings only within that boundary.