Streaming Search Results Into LLM Generation Pipelines
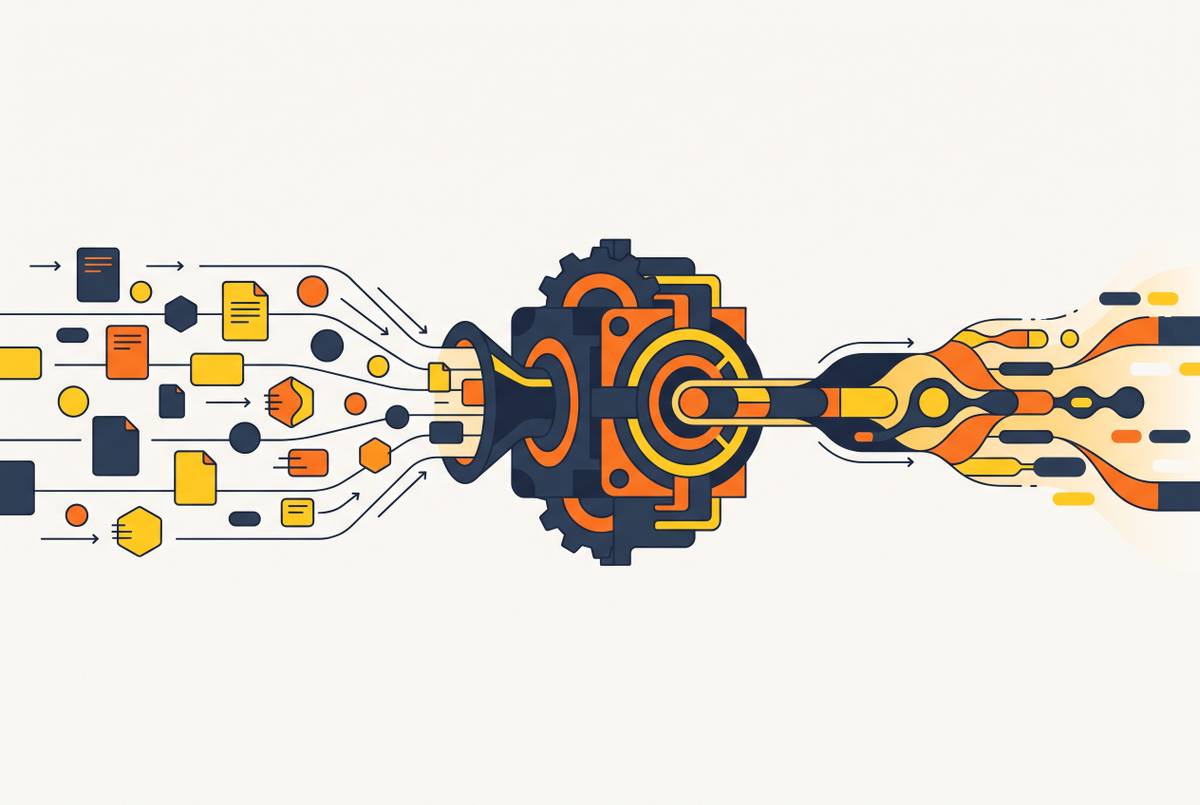
Stream search results into models without blocking retrieval or losing performance to buffering.
Marcus Oyelaran
Staff Writer, Search & Retrieval
Marcus worked as a backend engineer at two search-infrastructure startups before joining the editorial side in 2020, where he developed a reputation for unusually rigorous API benchmarks. His pieces on retrieval quality and index latency are required reading in several developer Slack communities.
3 stories
Stream search results into models without blocking retrieval or losing performance to buffering.
Why grounding and retrieval, not better models, fix hallucination in production.
Real-time web data keeps AI agents grounded in fact.